The Week I Stopped Trusting a Single Number
I spent Tuesday night trying to figure out why a fine-tune I ran over the summer got worse at something I never touched. Not catastrophically worse. Just quietly, embarrassingly worse on a handful of facts it used to get right. I had no story for it. I had a loss curve going down and a behavior going sideways, and the only tool I reached for was running the whole thing again with a different learning rate.
That is a bad habit, and this week’s reading made me feel appropriately called out. The thread running through everything I read is that the field is getting serious about locality: which specific parts of a model, or a training run, or an evaluation, are responsible for the thing you observed. Not the aggregate. The parts.
Attribution as an objective, not an audit
The piece that reframed the most for me is Matryoshka Attribution from Arora, Goodman, Jurafsky, Potts and coauthors. Interpretability methods usually feel like forensics: you run causal interventions or gradient attributions after the fact, and either it is too expensive to do at scale or it finds components that correlate with behavior without actually causing it. MAttr instead makes attribution a learning problem. You parametrize a mask over internal components with a differentiable sigmoid top-k, and here is the trick I keep turning over: you randomize k during training so the model is supervised at every sparsity level simultaneously. What falls out is not one mask but a nested ordering of components by importance, Matryoshka dolls all the way down.
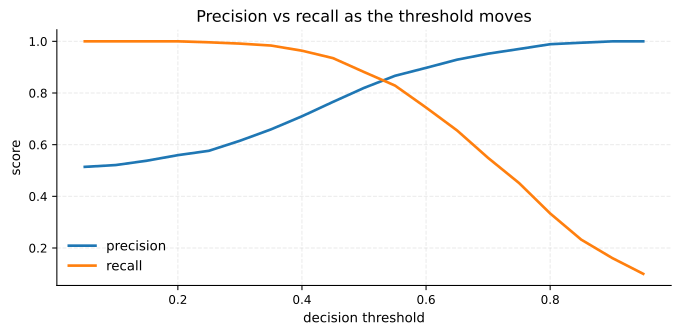
I love this because it dissolves a question I always found annoying. When someone shows me a circuit, my first instinct is “why those nodes and not fifty more?” Usually the answer is a threshold someone picked. Here the threshold is a dial the method was trained across, so the honest answer is a curve.
Then the application lands hard. They train MAttr with RL on refusal judge scores and find that reverting roughly one percent of Llama 3.1 8B Instruct’s weights back to the base model removes refusals while capabilities stay intact. One percent. I have two reactions at once. Scientifically this is a beautiful result: it says safety training, at least this kind, is stored somewhere shockingly concentrated rather than smeared across the network. Practically it is a little alarming, and I do not think the paper oversells or underplays it. The honest reading is that localization is a capability, and capabilities cut in whatever direction you point them.
The same idea, wearing a robotics hat
What surprised me was finding the localization instinct in a paper about latency. Dong, Hung, Sadigh and Finn’s Real-Time EXPO-FT attacks a problem that is almost physical: big vision-language-action models are slow, so by the time an action executes, the observation that chose it is stale. That staleness is a distribution shift, and it eats reliability on anything dynamic.
Their fix is to split the policy by timescale. The large pretrained VLA proposes action chunks using its strong behavior prior, and a small edit policy makes fast reactive corrections conditioned on the freshest observation. Average performance on four real tasks, including ball balancing and table soccer kicking, goes from 42 percent to 97 percent with under ten minutes of online robot data and no human intervention.
I keep coming back to how similar this is in spirit to MAttr. Both are saying: do not treat the network as one undifferentiated blob you have to push on uniformly. Find the small fast part that carries the decision-relevant signal, and let the big slow part supply the prior. In one case the goal is understanding, in the other it is control, but the structural claim is identical.
Structure predicts damage
My summer fine-tuning mystery has a name now, and it is in Popular Knowledge Propagates More Errors by Zhang, Ji, Zhai and coauthors. Prior work told us long-tail facts are hard to learn and hard to keep. This asks a sharper question: among facts the model already gets right, which are fragile? They build FACTPROP, a graph of verified Wikipedia facts linked by shared head or tail entities, and fine-tune while watching correct answers flip to incorrect.
The finding inverts my intuition. Facts attached to highly connected entities are the most vulnerable to corruption from neighboring updates, and damage to them spreads further. Popularity is not a moat, it is exposure. I had assumed well-represented facts were overdetermined by redundant training signal and therefore safe. Apparently being densely wired in means more gradient paths run through you. Their mitigation, PopAnchor, is a small rehearsal set of popular facts, and it is the kind of cheap intervention I want to try on a course project rather than admire from a distance.
The graph-structural framing also makes me slightly suspicious in a productive way. Wikipedia link topology is a proxy for popularity, not popularity itself, and I would want to see whether the effect survives when you decouple graph degree from pretraining frequency. That feels like a genuinely open question.
Reuse what you already proved
The unglamorous paper is the one I will probably use first. Bosman, Kwiatkowska, Hoos and van Rijn explore solver-level warmstarting for neural network verification. Verifying adversarial robustness is NP-complete, and in practice each query gets solved from scratch even when you are sweeping perturbation radii or nudging the network. Their pipeline carries solver state across related instances, cutting runtime in most cases and solving some instances that time out cold.
It is the same lesson as everything above: the expensive object is not the answer, it is the structure you discovered while getting there, and throwing it away every time is a choice.
Which brings me to the release I did not expect to care about. Hugging Face and UK AISI’s EvalEval collaboration publishes verified results with configuration and transcript-level detail across HealthBench, FrontierMath, Humanity’s Last Exam, SWE-Bench Pro and Terminal-Bench 2.0. The accompanying work on how inference compute shapes evaluation is the part that stung: performance on the same benchmark moves with the protocol, and when models got oracle correctness feedback between attempts they kept solving more tasks as token budgets grew. A leaderboard number without its setup is not a measurement, it is a rumor.
What I am taking away
Every one of these pushes against summarization. A single accuracy number hides which components produced it, a single loss curve hides which facts it quietly broke, a single verification result hides the work that could have been reused, and a single benchmark score hides the compute budget that bought it.
So the thing I want to try this semester is small: take one fine-tune I actually care about, build a tiny FACTPROP-style neighborhood around the facts I am updating, and track correct-to-incorrect flips as a first-class metric instead of an afterthought. I do not need MAttr-scale machinery to do that. I just need to stop accepting one number as an explanation.
Sources
- Matryoshka attribution: Learning to attribute language model outputs to representations and weights (Dan Jurafsky)
- Reinforcement Learning for Real-Time Vision-Language-Action Policies (Chelsea Finn)
- Exploring Solver-Level Warmstarting for Neural Network Verification (Marta Kwiatkowska)
- Popular Knowledge Propagates More Errors in LLM Knowledge Updating (ChengXiang Zhai)
- How UK AISI and EvalEval Are Making Benchmark Results Reproducible (Hugging Face)